Qwen3-TTS
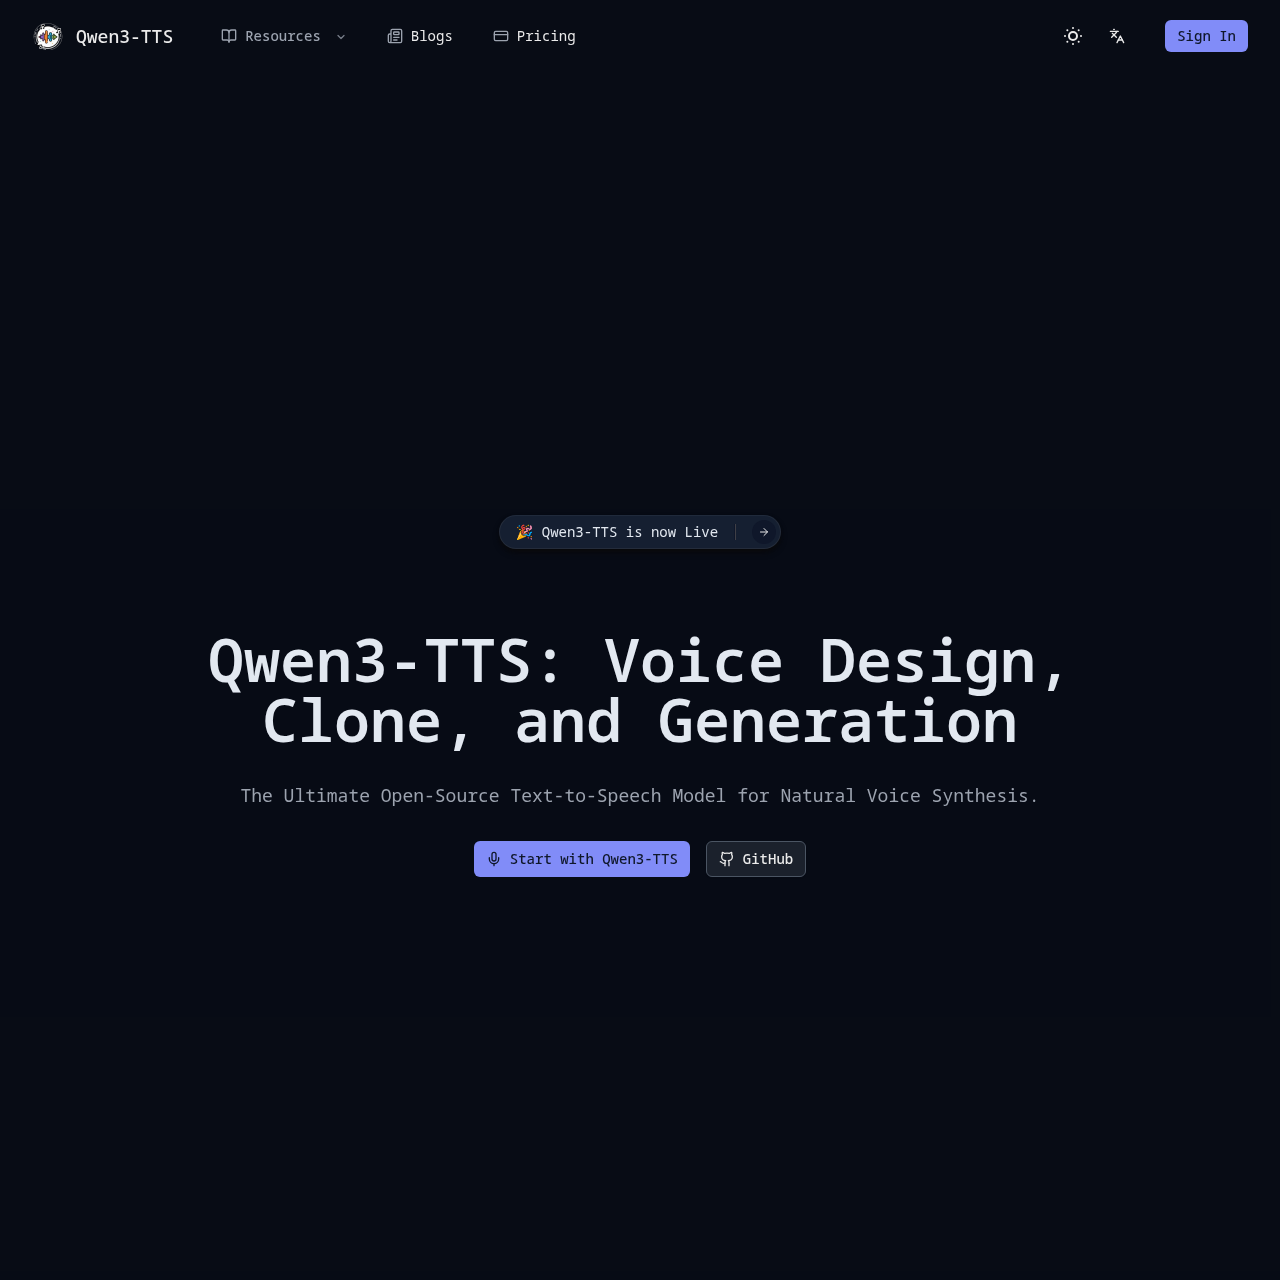
VisitVoice Design, Clone, and Generation
Qwen3-TTS introduction
Qwen3-TTS is the leading open-source text-to-speech model featuring zero-shot voice cloning, emotional control, and support for 10+ languages. Generate natural, human-like speech with ultra-low latency.
- Website:
- qwen3-tts.app
Qwen3-TTS overview
Qwen3-TTS is an open-source text-to-speech model for natural voice synthesis. It uses a high-efficiency 12Hz tokenizer and multi-codebook speech encoder to balance sample compression and detail retention, capturing paralinguistic features like breath, hesitation, and emotional intensity. It supports zero-shot voice cloning from a 3-second reference clip, context-aware prosody, multilingual synthesis in over 10 languages, and real-time streaming with 97ms first token latency. It offers Python SDK and OpenAI-compatible API for integration.
Qwen3-TTS features
- Zero-shot voice cloning from a 3-second reference clip
- Emotional control and natural language audio control (whisper, shout, laugh, speak fast)
- Multilingual synthesis in over 10 languages including English, Chinese, Japanese, Korean, French, and German
- Context-aware prosody and intonation
- High-efficiency 12Hz tokenizer
- Multi-codebook speech encoder
- Long-form audio synthesis
- Real-time streaming with 97ms first token latency
- Python SDK and OpenAI-compatible API
- Docker deployment for OpenAI-compatible API server
- Apache 2.0 open-source license
- Code-switching support
Questions about Qwen3-TTS
Qwen3-TTS pros
- Open-source under Apache 2.0 license
- Ultra-low 97ms first token latency
- Zero-shot voice cloning from a short reference clip
- Supports over 10 languages with code-switching
- Natural language control over emotion and style
- High-efficiency tokenizer and multi-codebook encoder for detail retention
- Easy integration via Python SDK and OpenAI-compatible API
- Long-form audio synthesis with consistency
Qwen3-TTS use cases
- Dynamic content creation requiring personalized voices
- Global applications and localized content generation
- Audiobooks, podcasts, and long video narrations
- Real-time AI voice bots
- Live translation devices
- Voice chat applications
- Drop-in replacement for existing TTS services
Who Qwen3-TTS is for
- Developers
- Startups
- Researchers
- Hobbyists
- Global application builders
- Real-time AI agent developers
Alternatives to Qwen3-TTS
AI podcast studio that turns any content into audio and video podcasts

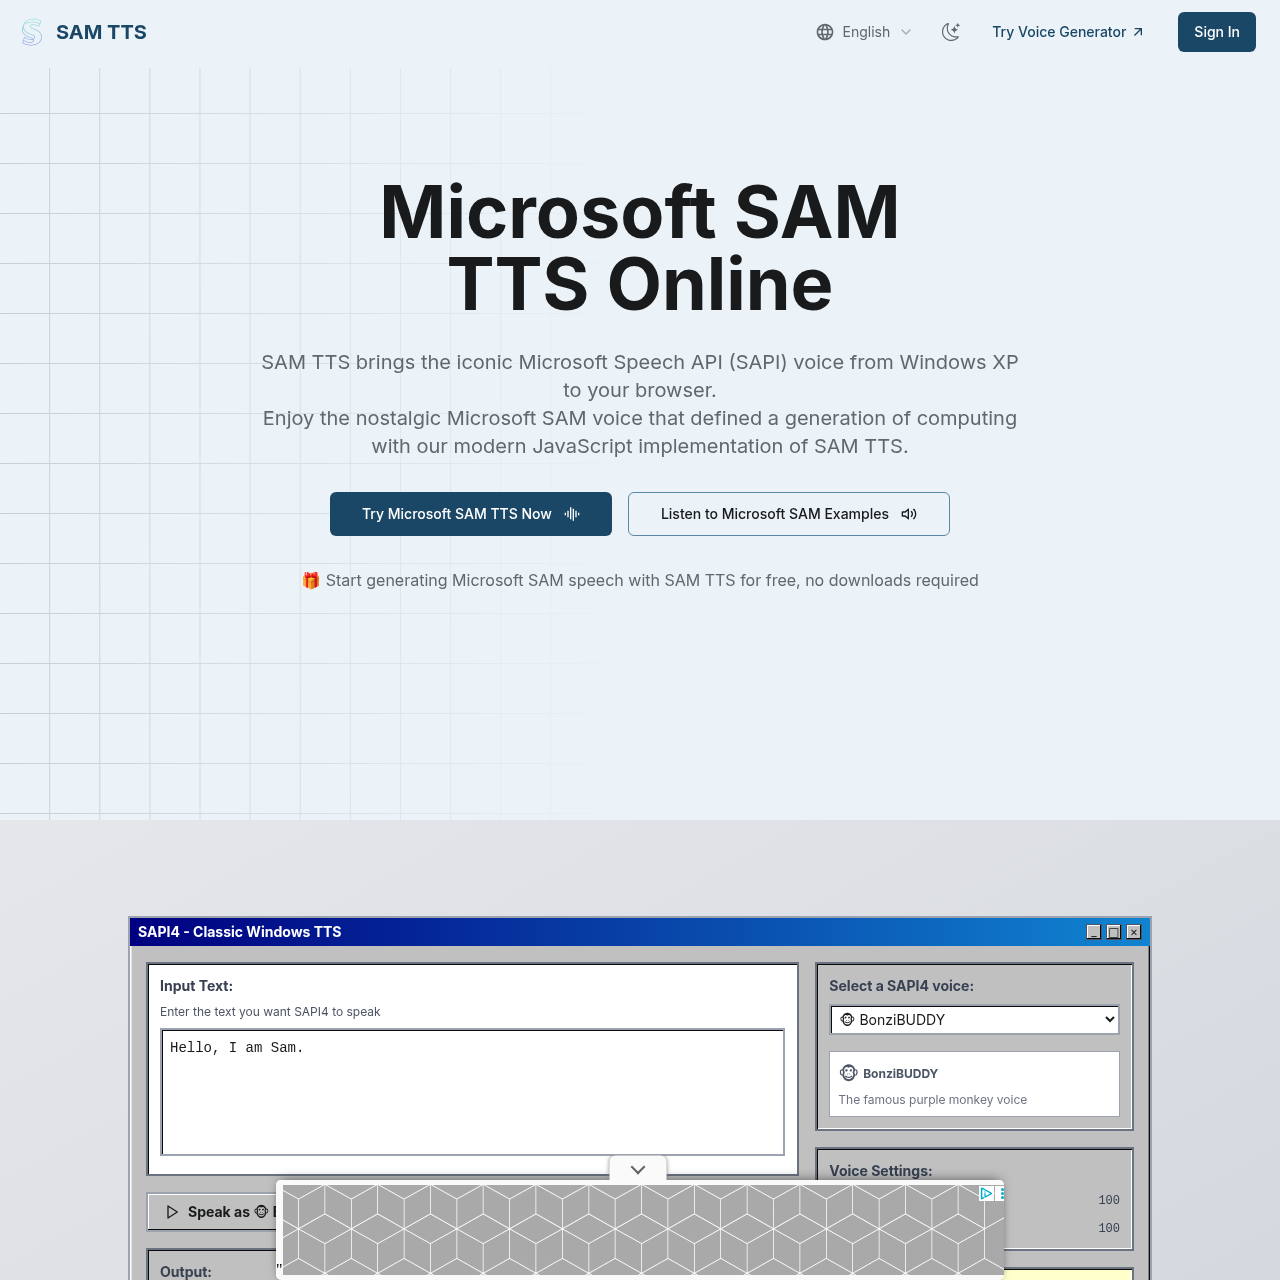
Free browser-based Microsoft SAM text-to-speech generator recreating the classic Windows XP voice.